

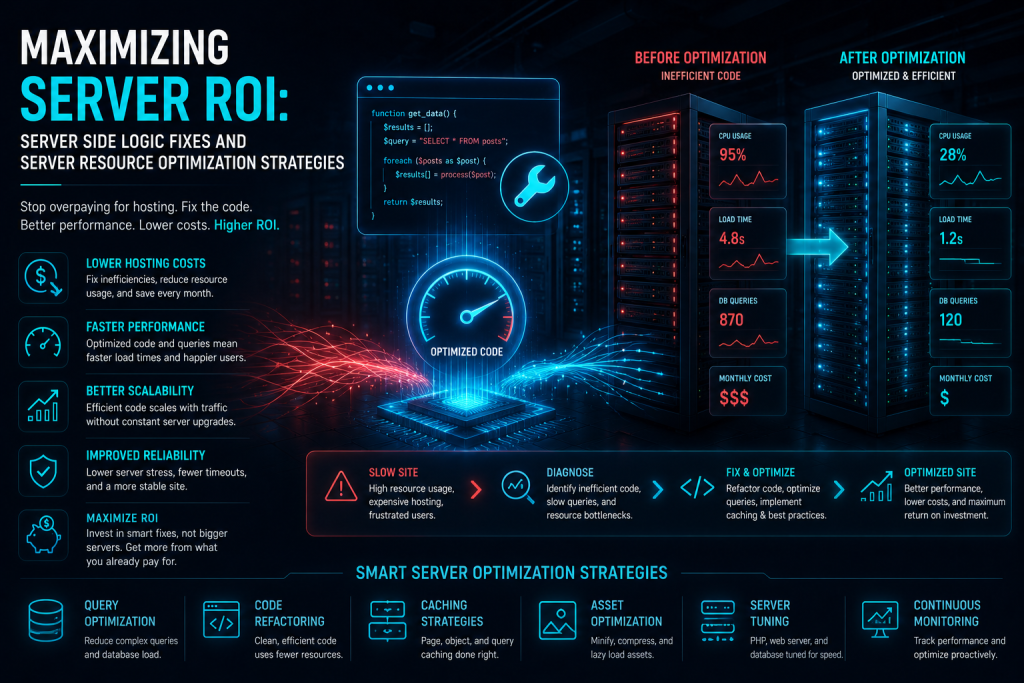
Maximizing Server ROI: Server Side Logic Fixes and Server Resource Optimization Strategies
Every CFO and operations director managing a growing WordPress site eventually has the same conversation with their technical team. The hosting bill has crept up again. Traffic has not grown proportionally to the cost increase, or worse, traffic has grown while the site’s performance has actually gotten slower despite the additional spend. The proposed solution, almost always, is the same one that was proposed the last time this conversation happened: upgrade to a bigger server plan. Approve the budget increase. The site will be fast again, at least for a while, until the same conversation repeats itself six months later.
This pattern is extremely common, and it reflects a fundamental misunderstanding that costs businesses real money year after year. Server resources are not the actual bottleneck in the vast majority of these situations. Inefficient backend code is. A bigger server plan gives inefficient code more room to run before it hits a wall, but it does not fix the inefficiency itself, which means the wall simply moves further out, and the business keeps paying an escalating hosting bill to compensate for a code problem that a larger server was never going to solve. This article is written specifically for CFOs, operations directors, and technical leads who want to understand why this happens, how to actually diagnose the real source of server resource consumption, and what genuine server side logic fixes look like, so that server budget gets spent on real growth rather than compensating for avoidable inefficiency.
The Hosting Upsell Trap
Upgrading a server plan is the path of least resistance whenever a WordPress site starts struggling under load. It requires no code review, no engineering investigation, and no uncomfortable conversation about whether the site’s underlying codebase might be the actual problem. It also, critically, tends to work, at least temporarily, which is exactly what makes it such an effective trap. A site that was struggling under a smaller server plan genuinely does perform better immediately after an upgrade, and this immediate, visible improvement reinforces the belief that the server tier was the problem all along.
Why an Upgrade Provides Only Temporary Relief
The reason this improvement is temporary rather than permanent comes down to a simple mechanical reality. Inefficient code, a slow database query running repeatedly, a poorly optimized custom function executing on every page load, a plugin performing redundant calculations it should be caching, consumes server resources at a rate that does not change based on how much server capacity is available. A bigger server simply provides more headroom before that inefficient consumption starts causing visible slowdowns or CPU spikes. The underlying inefficiency has not been touched at all. It is simply operating with more room to breathe, for now.
As traffic continues to grow, as more content and functionality get added to the site, and as the same inefficient code continues running on every relevant page load, that additional headroom gets consumed the same way the previous, smaller allocation did. The site slows down again. CPU spikes return. And the proposed solution, once again, is another server upgrade, because nobody has ever actually diagnosed or addressed the code level cause of the original problem. This cycle can repeat multiple times, each iteration costing more in monthly hosting fees, without the underlying inefficiency ever being identified or corrected.
The Real Cost of Chasing Server Tiers Instead of Fixing Code
It is worth being specific about what this cycle actually costs a business over time, because the framing of a single server upgrade as a modest, reasonable expense obscures the compounding financial impact of repeating this pattern year after year. A business that upgrades its hosting tier every six to twelve months, each time in response to the same underlying inefficiency continuing to consume whatever additional capacity was most recently purchased, is effectively paying an escalating, permanent tax on code that was never actually fixed. Over several years, this tax frequently exceeds, often by a significant margin, what a proper code level investigation and fix would have cost as a one time engineering engagement.
This is not a hypothetical scenario. It is one of the most common patterns encountered when a business finally brings in a technical team specifically to investigate why hosting costs keep climbing despite traffic growth that does not obviously justify the increase. The diagnosis is very often the same: a handful of specific, identifiable inefficiencies in custom code or poorly configured plugins, consuming a disproportionate share of server resources on every single page load, quietly driving the need for each successive server upgrade that finance has been approving without much scrutiny, simply because it has always been presented as the only available option.
Why This Trap Is Easy to Fall Into
Part of what makes this pattern so persistent is that server upgrades are genuinely easy to purchase and genuinely easy to justify to a finance team in the moment. A hosting provider’s sales team is generally happy to recommend a bigger plan whenever performance complaints arise, since it directly benefits their own revenue, and a bigger plan requires no uncomfortable conversation about whether the site’s own code might be the actual source of the problem. A code level investigation, by contrast, requires engineering expertise capable of actually profiling server resource consumption and reading through a site’s custom codebase, which represents a less familiar and less immediately reassuring proposition to a finance team accustomed to the simpler mental model of simply buying more capacity whenever more capacity seems to be needed.
This dynamic means the hosting upsell trap tends to persist specifically because nobody with the technical expertise to identify the real problem has ever been asked to look closely enough to find it. Breaking the cycle requires exactly that kind of investigation, treating persistent performance problems and escalating hosting costs as a code level engineering question rather than simply a capacity question to be solved through the next available upgrade.
Why Hosting Providers Rarely Flag the Real Problem
It is worth understanding why this dynamic persists so consistently across the hosting industry, since it is not necessarily a matter of bad faith on the part of any individual provider. Most hosting providers, even genuinely reputable ones, are structured around selling and supporting server capacity, not around auditing and fixing a customer’s application level code. Their support teams are typically well equipped to diagnose server configuration issues, confirm that resource limits are being reached, and recommend an appropriate tier increase to accommodate that resource usage. What they are generally not equipped or incentivized to do is dig into a customer’s specific custom plugins and theme code to determine whether that resource usage is actually necessary in the first place, or whether it reflects fixable inefficiency.
This is simply outside the scope of what a hosting relationship typically covers, and it means a business relying solely on its hosting provider for performance guidance will, almost by structural default, receive capacity focused recommendations rather than code focused ones, regardless of which one would actually solve the underlying problem more effectively and more permanently. Recognizing this structural gap is an important part of understanding why the upsell trap persists even among businesses working with genuinely competent, well intentioned hosting providers.
Tracking Resource Hogs
Before any code level fix can be applied, the actual source of excessive resource consumption has to be identified with precision. This is genuinely investigative work, closer to profiling and diagnostics in any serious software engineering discipline than to the kind of surface level troubleshooting most WordPress maintenance providers are equipped to perform.
Why Guessing at the Cause Wastes Time and Money
A common but ultimately wasteful approach to performance troubleshooting involves guessing at likely culprits based on general reputation, deactivating a plugin known to sometimes cause performance issues, adding a caching layer without first understanding what specifically needs to be cached, or simply optimizing images and calling the investigation complete. These general best practices are worth applying as a baseline, but they frequently fail to address the actual source of severe, ongoing resource consumption on a complex, custom developed site, because that source is often specific to the site’s own custom code or its particular combination of plugins interacting in an unexpected way, not a generic, widely known issue that a general checklist would reliably catch.
Time spent applying generic fixes that do not address the actual root cause is not free. It delays the point at which the real problem gets identified and fixed, all while the business continues paying for server capacity that inefficient code keeps consuming, and all while a finance team continues fielding requests for the next hosting tier upgrade because the underlying issue remains unresolved.
Server Level Profiling as the Starting Point
A proper investigation begins with actual measurement rather than guesswork, using server level profiling tools to observe exactly where CPU time, memory, and database query time are being consumed during real page loads. This kind of profiling produces concrete, specific data, identifying precisely which PHP functions are consuming the most execution time, which database queries are running most frequently or taking the longest to complete, and which specific requests or page types are responsible for the majority of a site’s overall resource consumption.
This data transforms an abstract complaint, the site is slow, hosting costs keep going up, into a specific, actionable finding, this particular custom function is being called on every single page load and performing an expensive calculation that could be cached, or this specific database query lacks a proper index and is scanning far more rows than necessary every time it runs. Specific findings like these are what actually lead to targeted, effective fixes, rather than the general, unfocused optimization efforts that so often fail to move the needle on the underlying problem.
Identifying Which Plugins Are Genuinely Expensive
Not every plugin contributes equally to a site’s total resource consumption, and a proper audit distinguishes clearly between plugins that are lightweight and efficient and those that are consuming a disproportionate share of server resources relative to the value they provide. This audit typically involves measuring each active plugin’s individual contribution to page load time and server resource consumption, identifying specific plugins that are performing unnecessary database queries on every page load regardless of whether their functionality is actually being used on that specific page, or running expensive processes on a schedule far more frequently than actually necessary for the plugin’s intended purpose.
This audit frequently surfaces plugins that were installed for a narrow, specific purpose but were never properly configured to limit their resource footprint, running background processes or database queries far beyond what their actual use case on the site requires. Identifying these specific inefficiencies allows for targeted remediation, whether through better configuration, replacing an inefficient plugin with a more efficient alternative, or in some cases building the specific needed functionality as lightweight custom code rather than continuing to carry a plugin’s broader, less efficient overhead for a narrow slice of functionality it was never optimized to deliver efficiently.
Auditing Custom Code and Theme Functions
For sites carrying genuine custom development, custom theme functions, bespoke plugins, business specific integrations, this category of code frequently represents the largest and most impactful source of resource consumption, precisely because it has never been reviewed by the broader community of WordPress performance specialists who continuously audit and improve the performance of widely used, publicly available plugins and themes. A custom function built quickly to meet an urgent business need, without particular attention to performance efficiency at the time it was written, can easily become one of the most expensive operations running on every single page load, quietly consuming a disproportionate share of server resources for years without anyone specifically investigating its performance characteristics.
A thorough audit reviews every piece of custom code running on the site, tracing exactly how often each function executes, what database queries or external requests it triggers, and whether its actual implementation reflects efficient coding practices or accumulated technical shortcuts taken under past time pressure. This is detailed, time consuming work, and it is precisely the kind of investigation that a generic maintenance provider, focused primarily on updates and basic troubleshooting, is rarely equipped to perform thoroughly.
Recognizing CPU Spike Patterns as Diagnostic Clues
The specific pattern of when CPU spikes occur often provides valuable diagnostic information before a single line of code is even examined. Spikes that consistently occur at a specific time of day, regardless of actual visitor traffic at that time, frequently point toward a scheduled background process, an automated backup, a synchronization task, a scheduled report generation, that is running inefficiently or too frequently. Spikes that correlate directly with visitor traffic volume, growing worse specifically during periods of higher site usage, more often point toward inefficient code running on frequently visited pages, since that inefficiency compounds directly with however many visitors happen to be triggering it simultaneously.
Spikes that occur on specific actions, checkout completion, search queries, form submissions, rather than simple page views, point toward inefficiency in the specific backend logic handling that particular action, narrowing the investigation considerably before any detailed profiling work even begins. Learning to read these patterns, drawing on server monitoring data and access logs correlated against actual site activity, is an important diagnostic skill that turns a vague, general performance complaint into a focused, specific starting point for the deeper technical investigation that follows.
Continuous Monitoring Versus a Single Point in Time Audit
A single audit, conducted at one point in time, provides a valuable snapshot, but resource consumption patterns on a growing, actively developed site are rarely static. New features get added. Content volume grows. Traffic patterns shift with marketing campaigns and seasonal demand. A resource inefficiency that was minor at the time of an initial audit can become a significant contributor to server costs months later, simply because the surrounding conditions, traffic volume, content volume, changed enough to amplify its impact.
This is why genuine server resource optimization benefits from ongoing monitoring rather than treating the initial audit as a one time, complete solution. Continuous monitoring tracks resource consumption trends over time, flagging new inefficiencies as they emerge, whether introduced through a new feature, a new plugin, or simply the natural growth of existing functionality reaching a scale where an existing inefficiency finally becomes noticeable. Businesses that treat server optimization as an ongoing discipline, rather than a single project completed once, are considerably less likely to find themselves back in the same hosting upsell cycle a year or two after their initial optimization engagement.
Implementing Server Side Logic Fixes
Once the specific sources of excessive resource consumption have been identified through proper profiling and audit, the actual remediation work begins. This section walks through the most common categories of server side logic fixes that produce measurable improvements in CPU consumption, database load, and overall server efficiency.
Eliminating Redundant Loops and Repeated Calculations
A surprisingly common source of unnecessary CPU consumption is code that performs the same calculation or the same data retrieval multiple times within a single page load, when the result could have been calculated once and reused. This often happens gradually, as different features get added to a site over time by different developers who were not necessarily aware that a similar calculation was already being performed elsewhere on the same page. The fix typically involves restructuring the code to calculate a given value once, store the result temporarily, and reuse that stored result everywhere it is needed within that same page load, rather than repeating the same expensive operation multiple times unnecessarily.
Nested loops, where one loop runs inside another, deserve particular attention during this kind of review, since their computational cost can grow dramatically as the amount of data being processed increases. Code that performs acceptably during initial development and testing, when working with a small amount of sample data, can become a severe performance bottleneck once a site’s actual content or user base grows substantially larger, precisely because the computational cost of a poorly structured nested loop scales far more steeply than a simple, single pass through the same data would.
Fixing Inefficient Database Queries
Database query optimization is frequently the single highest impact category of server side logic fix, since inefficient queries directly consume both CPU time and database server resources, and their cost tends to scale directly with a site’s content volume and traffic, meaning an inefficient query that seemed tolerable at a smaller scale can become a severe bottleneck as the site grows. Common issues include queries that lack proper database indexing, forcing the database to scan through far more rows than necessary to find the relevant data, queries that retrieve significantly more data than the code actually needs and then discard most of it after retrieval, and queries that get executed repeatedly within a loop when a single, properly structured query could have retrieved all the necessary data at once.
Fixing these issues requires genuine database expertise, understanding how to read a database’s query execution plan to identify exactly why a particular query is running inefficiently, knowing when and how to add proper indexing without introducing new problems elsewhere, and restructuring queries to retrieve exactly the data actually needed rather than over fetching and processing unnecessary data after the fact. This is meticulous, detail oriented engineering work, and the resulting performance improvement is often dramatic, sometimes reducing a single query’s execution time by an order of magnitude or more once properly optimized.
Reducing Unnecessary External Requests
Many performance problems stem not from the WordPress site’s own code directly, but from external requests that code makes to other services during page generation, calling a third party API, fetching data from an external source, or communicating with an integrated service. When these external requests are not properly cached, and especially when they are made synchronously, meaning the page cannot finish loading until the external request completes, they introduce both a direct performance cost and a significant risk factor, since a slow or unresponsive external service can directly degrade the performance of the WordPress site itself, regardless of how efficient the site’s own code otherwise is.
Server side logic fixes in this category typically involve implementing proper caching for external request results, so that repeated requests for the same data do not trigger a new external call every time, restructuring synchronous requests to happen asynchronously where the site’s functionality allows for it, and building in proper fallback behavior so that a slow or failed external request degrades gracefully rather than causing the entire page to hang or fail while waiting for a response from a service outside the business’s own control.
Optimizing How Plugins Interact With Each Other
Individual plugins that each perform reasonably efficiently in isolation can still produce significant combined overhead when their interactions are not properly considered, multiple plugins independently querying overlapping data, multiple plugins each registering their own scheduled background processes without coordination, or multiple plugins each loading their own version of a shared library unnecessarily. Addressing this category of inefficiency often involves consolidating redundant functionality, configuring plugins to share cached data rather than independently retrieving the same information multiple times, and carefully scheduling background processes to avoid multiple resource intensive tasks running simultaneously and competing for the same limited server resources.
A Disciplined, Measured Approach to Implementation
Applying server side logic fixes effectively requires a disciplined process, not a series of isolated, ad hoc changes made in response to whatever seems most obviously inefficient at first glance. Each proposed fix should be tested in a staging environment first, measured against the same profiling tools used during the initial audit to confirm the fix actually produces a measurable improvement, and verified to ensure it has not introduced any new functional issues elsewhere on the site. This measured approach ensures that engineering time is spent on fixes that produce genuine, verified impact, rather than changes that feel intuitively like they should help but have not actually been confirmed to move the needle on real, measured server resource consumption.
Caching for True ROI
Server side logic fixes address the root cause of inefficient resource consumption directly. Properly implemented caching complements this work by ensuring that even efficient, well optimized code does not need to run more often than genuinely necessary, avoiding repeated execution of the same logic and the same database queries for requests that could be served from a previously computed, cached result instead.
Why Basic Page Caching Is Not Enough for Complex Sites
Most WordPress sites implement some form of basic page caching, storing a static copy of a fully rendered page so that subsequent visitors receive that stored copy rather than triggering a full page regeneration on every single request. This works well for genuinely static content, but it becomes considerably less effective for sites with significant dynamic content, personalized experiences, frequently changing data, or logged in user functionality, all of which either cannot be cached through basic page caching at all or require the cache to be invalidated and regenerated so frequently that much of its benefit is lost.
For complex, high traffic sites, particularly those with ecommerce functionality, membership features, or personalized dashboards, basic page caching alone leaves a significant share of server resource consumption completely unaddressed, since a meaningful portion of what the site actually does on every page load simply cannot be served from a static, cached page in the first place.
Object Caching With Redis or Memcached
Object caching addresses this gap directly, operating at a more granular level than full page caching by storing the results of specific, expensive database queries and computations in fast access memory, using dedicated caching systems like Redis or Memcached specifically designed for this purpose. Rather than caching an entire rendered page, object caching allows individual pieces of data, the result of a specific expensive query, a computed value used across multiple pages, session specific data, to be cached and retrieved quickly, even on pages that cannot be fully cached through basic page caching due to their dynamic or personalized nature.
Properly configured object caching frequently produces one of the largest single improvements available in a server optimization engagement, precisely because it addresses the specific, repeated database queries and computations identified during the resource audit described earlier in this article, without requiring those underlying operations to be entirely eliminated, only executed once and then served from cache for subsequent requests within the cache’s configured lifetime. This is particularly valuable for sites where basic page caching has already been implemented but performance issues persist, since it directly targets the dynamic functionality that page caching alone was never able to address.
Bypassing Heavy PHP Generation With Cloudflare and Edge Caching
Beyond server level caching, implementing a content delivery network and edge caching layer, commonly through a service like Cloudflare, provides an additional layer of protection against unnecessary server resource consumption by serving cacheable content directly from a global network of edge servers, without the request ever needing to reach the origin server and trigger PHP execution at all. For content that can be safely cached at the edge, static assets, and in many cases full pages for anonymous, non personalized visitors, this approach dramatically reduces the actual load reaching the WordPress server itself, since a significant share of total traffic can be served entirely from the edge cache without ever consuming origin server CPU, memory, or database resources.
This layered approach, edge caching handling as much traffic as possible before it ever reaches the origin server, object caching handling the dynamic, uncacheable requests that do reach the server efficiently, produces a meaningfully different resource consumption profile than relying on origin server capacity alone to handle every single request directly. For a business evaluating hosting costs, this layered caching strategy often allows a site to comfortably handle several times its current traffic volume on the same server tier it is currently running, directly addressing the CPU spikes and slow speeds that would otherwise be driving the case for yet another hosting upgrade.
Configuring Caching Correctly for Genuine ROI
It is worth being direct about a common failure mode here. Caching implemented carelessly, without properly accounting for a site’s specific dynamic functionality, can create its own set of problems, serving stale data to users, breaking personalized features, or creating confusing inconsistencies between what different visitors see. Genuine ROI from a caching strategy requires careful configuration specific to the site’s actual functionality, correctly identifying what can be safely cached and for how long, what needs to bypass cache entirely for correctness, and how cache invalidation should be triggered when underlying data actually changes, so that the performance and cost benefits of caching are realized without introducing new functional problems that then require their own separate remediation effort.
Balancing Freshness Against Performance
Every caching decision involves a tradeoff between serving data as quickly as possible and ensuring that data remains accurately current. A product price displayed from a cache that has not yet refreshed after a price change, or an inventory count that briefly shows outdated availability, represents exactly the kind of correctness risk that makes some businesses hesitant to implement aggressive caching in the first place. Properly designed caching strategies address this directly rather than treating it as an unavoidable cost of better performance, using short, carefully calibrated cache lifetimes for data that changes frequently and needs to remain accurate, longer cache lifetimes for data that changes rarely, and explicit, immediate cache invalidation triggered automatically whenever specific underlying data actually changes, rather than relying solely on a fixed time based expiration that might leave stale data visible longer than acceptable.
This calibration work, matching cache duration and invalidation strategy to the specific correctness requirements of each different type of data on a site, is precisely what separates a genuinely well configured caching architecture from a generic, one size fits all caching plugin installation that either caches too conservatively to produce meaningful performance benefit, or too aggressively, creating the exact correctness problems that make some technical teams reluctant to trust caching at all.
Cache Warming to Avoid a Slow First Request
A subtle but important consideration in caching architecture is what happens the moment a cache expires or is invalidated, when the next request for that data has to be served the slow way while the cache repopulates. On a high traffic site, this can mean a meaningful number of visitors experience the slow, uncached version of a page or query during the brief window immediately following cache expiration, particularly if that expiration happens to coincide with a period of high traffic. Cache warming addresses this by proactively regenerating cached content before it actually expires, or immediately after an invalidation is triggered, rather than waiting passively for the next visitor’s request to trigger regeneration and absorbing that slower response themselves.
This kind of proactive cache management requires deliberate engineering design rather than default plugin configuration, but it meaningfully improves the consistency of a site’s performance, ensuring that the benefits of caching are experienced reliably by every visitor rather than being undermined periodically by the specific unlucky visitor who happens to arrive right as a cache entry expires and needs to be regenerated.
Turning Server Optimization Into a Measurable Financial Outcome
For CFOs and operations directors evaluating whether an investment in server side logic fixes and proper caching architecture is worthwhile, it helps to translate the technical work described throughout this article into concrete financial terms, since the value of this kind of engineering work is ultimately measured in avoided and reduced hosting costs, not simply in abstract performance metrics.
Calculating the True Cost of the Upsell Cycle
Start by reviewing the site’s hosting cost history over the past two to three years, specifically noting each tier upgrade and the stated reason behind it at the time. In most cases where the underlying code inefficiency was never addressed, this history reveals a clear pattern, recurring upgrades roughly correlated with recurring performance complaints, without a corresponding, proportional increase in actual traffic or business activity that would independently justify the added capacity. The cumulative cost of this pattern, summed across every upgrade the business has approved to date, frequently represents a substantial, entirely avoidable expense once the underlying code inefficiency is properly identified and fixed.
Comparing the Cost of Investigation Against the Cost of the Next Upgrade
A useful framing for finance teams evaluating this decision is comparing the one time cost of a proper server resource audit and remediation engagement against the ongoing, recurring cost of the next hosting tier upgrade, and the tier after that, which history suggests is likely to be needed again within a similar timeframe if the underlying inefficiency remains unaddressed. In the majority of cases involving genuine, identifiable code level inefficiency, the one time engineering investment pays for itself well within the first year through reduced hosting costs alone, before even accounting for the additional benefit of improved site performance, better Core Web Vitals scores, and the reduced risk of a severe CPU spike causing an outage during a critical traffic period.
Why This Investment Compounds in the Business’s Favor
Unlike a hosting tier upgrade, which simply provides more room for the same inefficiency to continue consuming resources at the same underlying rate, a genuine server side logic fix permanently reduces how much server resource the site’s core functionality actually requires. This means the benefit compounds favorably as the business continues to grow. Traffic growth that would previously have triggered another hosting upgrade, because inefficient code was consuming a disproportionate share of available capacity, can instead be absorbed comfortably within the existing, properly optimized infrastructure, extending the useful life of the current hosting tier considerably longer than it would have lasted under the unaddressed inefficiency that was driving the previous upgrade cycle.
How Ongoing Optimization Fits Within a Resolution Based Model
Server resource optimization is rarely a single, complete project with a defined finish line. New inefficiencies can emerge as a site continues to grow, new features get added, and traffic patterns evolve. This is precisely the kind of ongoing, technically demanding work that fits naturally within a resolution based support model rather than being treated as a separate, unpredictably priced engagement every time a new performance concern arises. A slow query discovered six months after an initial audit, a newly added feature that turns out to carry an unexpected resource cost, a plugin update that introduces a new inefficiency, all of these are exactly the kind of complex technical issues that a resolution based plan is built to absorb, diagnosed and fixed as part of a predictable monthly cost rather than generating a new, unpredictable invoice every time server performance needs attention.
For CFOs and operations directors who have grown understandably wary of open ended, unpredictable technical spending, this predictability matters as much for performance engineering as it does for any other category of ongoing WordPress support. It transforms server optimization from a periodic, disruptive project into a continuous, budgeted discipline, exactly the kind of steady, proactive maintenance that prevents the hosting upsell cycle from ever re establishing itself in the first place.
Hosting Upgrades Versus Server Side Logic Fixes
| What You Care About | Another Hosting Upgrade | Server Side Logic Fix |
|---|---|---|
| Addresses the root cause | No, only adds capacity | Yes, reduces actual resource consumption |
| Cost pattern over time | Recurring, escalating | One time investment, lasting benefit |
| Effect on future traffic growth | New headroom fills again | More traffic absorbed on same tier |
| Effect on Core Web Vitals | Marginal, temporary | Direct, measurable improvement |
| Risk during future traffic spikes | Same underlying risk remains | Genuinely reduced load per request |
What This Looks Like in Practice
Consider a growing ecommerce business that has upgraded its hosting plan three times over the past two years, each time in response to CPU spikes and slow checkout performance during periods of increased traffic. Despite each upgrade providing temporary relief, the same pattern of complaints has returned within a matter of months following every single upgrade, and the CFO has finally requested a proper technical investigation before approving yet another tier increase.
A server level profiling audit reveals the actual source of the problem clearly within the first phase of investigation. A custom product recommendation feature, built to display related products on every product page, is running an inefficient, unindexed database query on every single page load, and that query’s execution time grows worse as the product catalog continues expanding, exactly the kind of degradation that would not have been obvious during initial development with a much smaller test catalog. Compounding this, a separate inventory synchronization plugin is running a full inventory check on a schedule far more frequent than the business’s actual inventory update needs require, consuming significant server resources at regular intervals throughout the day regardless of whether inventory has actually changed.
Remediation involves properly indexing the database table the recommendation feature queries and restructuring the query itself to retrieve only the specific data actually needed, reducing that particular operation’s execution time dramatically. The inventory synchronization schedule is adjusted to match the business’s actual update frequency, eliminating a significant share of unnecessary background resource consumption. Object caching through Redis is implemented specifically to cache the product recommendation results, since the same recommendations do not need to be recalculated on every single page view from every single visitor. Combined, these fixes reduce the site’s overall CPU consumption enough that the business is able to downgrade from its most recent, most expensive hosting tier back to a smaller plan, immediately reducing monthly hosting costs while simultaneously improving site performance during the exact high traffic periods that had previously been causing the recurring complaints in the first place.
A Checklist for CFOs and Operations Directors
For financial and operational leaders trying to determine whether their own organization is caught in the hosting upsell trap, a few direct questions help surface the answer. Has the hosting plan been upgraded more than once within the past two years without a proportional, independently verifiable increase in traffic or business activity driving that need. Has anyone with genuine engineering expertise actually profiled the site’s server resource consumption to identify specific inefficient code, or has every performance complaint been addressed exclusively through capacity increases. Do CPU spikes and slow performance tend to correlate with specific times, specific pages, or specific traffic patterns that could point toward a particular piece of functionality being the actual culprit. Is object caching currently implemented, and if so, is it actually configured around the site’s specific, identified performance bottlenecks, or was it installed generically without a targeted configuration. And has anyone calculated the cumulative cost of the hosting upgrade history against what a proper code level investigation and fix would likely have cost as a one time engineering engagement.
A single yes among these questions is worth investigating further. Multiple yes answers, particularly a pattern of recurring upgrades without a clear, independently verified traffic justification, strongly suggest that server budget has been compensating for unaddressed code inefficiency for some time, representing a genuine, quantifiable opportunity for cost reduction through proper engineering investigation rather than continued reliance on the next available hosting tier upgrade.
Frequently Asked Questions About Server Resource Optimization
How long does a proper server resource audit typically take
The timeline depends on the complexity of the site and the amount of custom code involved, but a thorough audit, including server level profiling, database query analysis, and a review of custom code and plugin behavior, generally requires enough time to gather meaningful data across representative traffic patterns rather than a single snapshot, since some inefficiencies only become visible under real, varied traffic conditions rather than in a brief, isolated test.
Will fixing inefficient code guarantee we never need another hosting upgrade
Genuine business growth, increased traffic, expanded functionality, a larger content or product catalog, will eventually require additional server capacity regardless of how efficient the underlying code is, since real growth genuinely does require more resources to serve. What proper server side logic fixes eliminate is the artificial, avoidable portion of that resource consumption, ensuring that any future hosting upgrade reflects genuine business growth rather than compensating for inefficiency that could have been fixed at the code level instead.
Is it risky to make changes to database queries and server side logic on a live, high traffic site
Any change to core site functionality carries some risk if implemented carelessly, which is precisely why a disciplined process, testing every fix in a staging environment first and verifying its impact before deploying to production, matters as much for performance engineering as it does for any other category of site change. Proper server side logic fixes are implemented with the same testing rigor as any other significant code change, specifically to avoid introducing new problems while resolving the original performance issue.
How is object caching different from the caching plugin many WordPress sites already use
Many popular WordPress caching plugins focus primarily on full page caching, storing a complete, rendered copy of a page for repeat delivery. Object caching operates at a more granular level, caching specific pieces of data, individual query results, computed values, session information, that full page caching cannot address, particularly on pages with dynamic or personalized content that cannot be safely cached as a complete, static page. The two approaches are complementary, and a genuinely well optimized site typically implements both together rather than relying on either one alone.
Can server side optimization work be done without any downtime or disruption to the live site
Yes, when implemented properly through a disciplined deployment process. Every fix is developed and tested in a staging environment first, confirming both its performance impact and its functional correctness before it is ever deployed to the live production site, and deployment itself follows the same controlled, tested process used for any other significant site change, specifically to avoid introducing unplanned downtime during the optimization process.
How do we know whether our hosting costs are actually justified by traffic growth or are being driven by inefficiency
The clearest signal is comparing the rate of hosting cost increase against the rate of genuine business growth, meaningful traffic increase, expanded product catalog, growing user base, over the same period. When hosting costs are climbing significantly faster than any of these underlying business metrics, that gap is a strong indicator that inefficiency, not legitimate growth, is driving the increased resource consumption. A proper server resource audit can confirm this directly by measuring exactly how much of current resource consumption reflects genuinely necessary work versus avoidable inefficiency.
What is the difference between database query optimization and simply adding more database server resources
Adding more database server resources, similar to a general hosting upgrade, provides more capacity for the same inefficient queries to continue running, without addressing why those queries are consuming more resources than necessary in the first place. Query optimization addresses the root cause directly, restructuring the query itself and ensuring proper indexing so that the same result is retrieved using meaningfully fewer database resources, producing a permanent efficiency improvement rather than temporary headroom that inefficient queries will eventually fill again as data volume and traffic continue to grow.
Should smaller businesses with lower traffic still be concerned about server side logic fixes
Smaller businesses with genuinely low traffic and simple functionality are less likely to experience severe consequences from moderate code inefficiency, since the absolute resource consumption involved remains manageable even without optimization. However, inefficiency that goes unaddressed tends to become significantly more costly precisely as a business succeeds and grows, which means addressing it early, before traffic and complexity scale up, is generally far less disruptive and less expensive than waiting until inefficiency has become a severe, urgent problem directly limiting the business’s ability to handle its own growth and success.
How often should a business revisit server resource optimization once an initial engagement is complete
Given that new inefficiencies can emerge as a site evolves, ongoing monitoring combined with periodic, deliberate review, particularly following significant new feature development, major traffic growth, or a series of plugin updates, helps ensure that the benefits of an initial optimization engagement are not gradually eroded by newly introduced inefficiency accumulating unnoticed over subsequent months and years of continued site development.
Stop Throwing Money at Bigger Hosting Plans to Mask Bad Code
The businesses that finally break the hosting upsell cycle are the ones that stop treating every performance complaint as a capacity problem and start treating it as an engineering question worth investigating properly. A bigger server plan will always provide some temporary relief, which is exactly what makes it such an easy, tempting default response. But temporary relief that recurs every six to twelve months, at an escalating cost, is not actually solving anything. It is compensating, indefinitely and expensively, for a code level problem that a proper audit, targeted server side logic fixes, and a genuinely well configured caching architecture can resolve permanently, protecting both the site’s performance and the business’s server budget at the same time.
A Different Way to Evaluate Every Future Performance Complaint
Perhaps the most valuable long term outcome of properly diagnosing and fixing server side inefficiency is not the immediate cost savings, meaningful as those typically are, but the shift in how future performance complaints get evaluated. A business that has been through a proper server resource audit, and has seen firsthand how a specific, identifiable code inefficiency was driving what previously looked like an unavoidable capacity problem, approaches the next performance complaint very differently. Instead of defaulting immediately to a hosting tier upgrade, the instinct becomes asking a more precise question first, has this been profiled, do we know specifically what is consuming these resources, or are we about to spend money compensating for a problem nobody has actually diagnosed yet.
This shift in default thinking, from capacity first to diagnosis first, is ultimately what protects a growing business from repeating the same expensive cycle indefinitely. It does not mean every future performance issue will turn out to be a code level fix rather than a genuine need for additional capacity. Real growth does eventually require real additional resources. But it means that decision gets made with actual evidence behind it, rather than as the automatic, unexamined default response to any performance complaint that happens to arise, which is precisely the pattern that allows avoidable inefficiency to quietly drive a hosting budget upward for years without anyone ever stopping to ask whether the code itself might be the actual problem.
Making This a Standing Practice, Not a One Time Project
The businesses that get the most lasting value from this kind of engineering investment treat it as an ongoing discipline rather than a single audit performed once in response to a particularly painful hosting bill. Server resource efficiency, like security hardening and deployment discipline covered elsewhere in our engineering guidance, benefits from continuous attention as a site grows, rather than being revisited only when costs have already escalated to an uncomfortable degree. Building this kind of proactive monitoring and review into a standing engineering relationship is what ultimately keeps a growing business’s hosting costs genuinely aligned with its actual, legitimate resource needs, rather than quietly inflated by inefficiency that nobody ever specifically looked for.
Stop Throwing Money at Bigger Hosting Plans to Mask Bad Code
Get an instant WordPress audit and let our engineering team perform server side logic fixes that protect your performance and your budget.
