

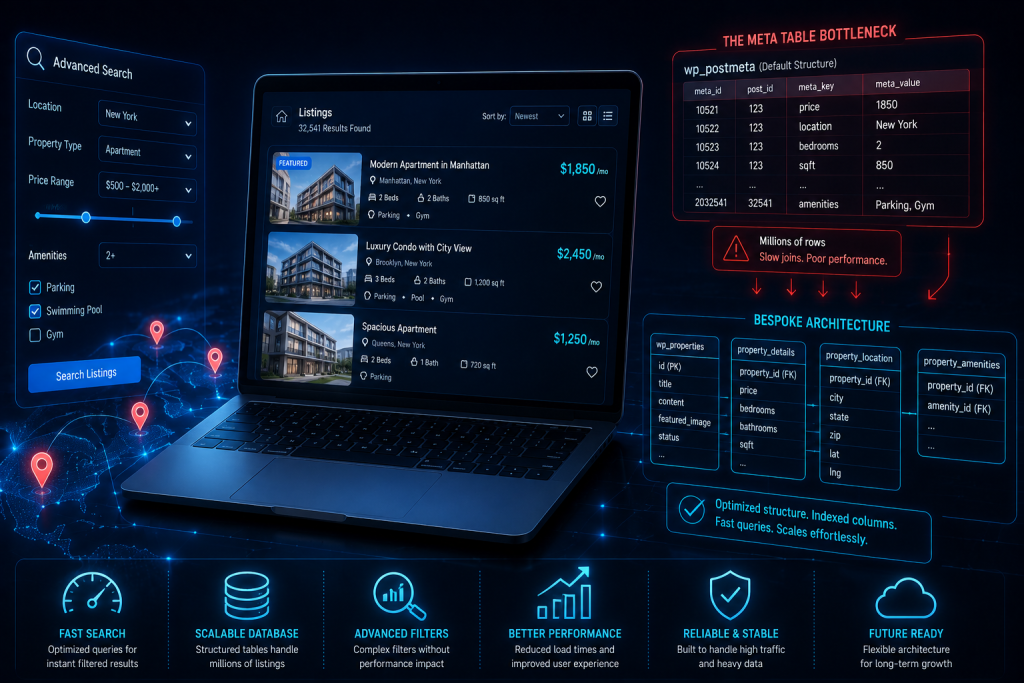
Architecting High Volume Directories: Scaling Custom WordPress Post Types and Complex Taxonomies
Every directory, listing, or catalog platform built on WordPress follows a remarkably similar trajectory. In the early days, with a few hundred or even a few thousand listings, everything works beautifully. Custom post types organize the content cleanly. Custom fields capture every piece of relevant listing data. Taxonomies handle categorization and filtering exactly as expected. Then the platform grows. Ten thousand listings becomes thirty thousand. Search filters that once returned results instantly start taking several seconds. The admin dashboard becomes noticeably heavier every time a new listing is added. And at some point, usually during a period of genuine business success rather than failure, the platform’s underlying database architecture simply cannot keep pace with the scale the business has actually achieved.
This article is written specifically for product managers and businesses running directory, listing, or large scale catalog portals on WordPress, walking through exactly why this slowdown happens at the database level, what bespoke architecture built specifically to handle this scale actually looks like, how custom search logic replaces the default WordPress approach that was never designed for tens of thousands of richly structured listings, and what real world scale for a WordPress powered directory platform genuinely looks like when the underlying architecture is built correctly from the start.
The Meta Table Bottleneck
To understand why large directory platforms eventually hit a serious performance wall, it helps to understand precisely how WordPress stores the custom field data that every listing, property, product, or catalog entry depends on, and why that default storage mechanism, while perfectly reasonable for smaller sites, becomes a genuine architectural liability at real directory scale.
How WordPress Stores Custom Field Data by Default
WordPress stores custom field data, whatever specific attributes a listing carries, price, square footage, location coordinates, amenities, availability status, in a single, shared database table commonly used across the entire site, structured as a simple key and value pairing associated with a specific post. This design is elegant in its simplicity and works well for typical WordPress use cases, where a site might have a modest number of posts, each carrying a modest number of custom fields. The same design becomes fundamentally strained once a site scales into the range of tens of thousands of listings, each carrying dozens of distinct custom fields, because every single one of those field values is stored as an individual row in this same shared table, meaning a directory with thirty thousand listings and forty custom fields per listing can easily accumulate well over a million rows in this single table alone.
Why This Table Structure Makes Filtering Expensive
The real performance cost of this architecture becomes apparent specifically when a visitor applies a filtered search, looking for listings within a specific price range, a specific location, with a specific set of amenities, which is precisely the core functionality any serious directory platform depends on. Because every custom field value lives in the same shared table, structured generically rather than in dedicated, purpose built columns, retrieving listings that match multiple filter criteria simultaneously requires the database to join this same large table against itself multiple times, once for each filter criterion being applied. A search filtering by price range, location, and two specific amenities requires the underlying query to join this same sprawling table four separate times within a single query, and each of these joins operates against a table that may contain millions of rows once the directory has scaled to a meaningful size.
This joining pattern, while functionally correct, is fundamentally expensive from a database performance perspective, and the cost compounds directly with both the total number of listings in the directory and the number of distinct filter criteria a visitor applies simultaneously. A directory with a thousand listings barely notices this cost. The same directory at thirty thousand listings, with visitors commonly applying four or five simultaneous filters through a rich search interface, experiences exactly the kind of painfully slow search response that becomes impossible to ignore once it starts directly affecting visitor experience and, ultimately, conversion rates on a platform where fast, responsive search is often the single most important feature the entire business depends on.
Why Indexing Alone Cannot Fully Solve This Problem
A natural first response to this kind of slowdown is adding database indexes to improve query performance, and proper indexing genuinely does help to a meaningful degree. However, the generic, shared structure of the default WordPress custom field table limits how effectively indexing alone can resolve the underlying problem, since the table’s structure, storing every field’s value as a generic text string regardless of the field’s actual data type, prevents the kind of precise, type specific indexing that a dedicated, purpose built column structure would allow. A price field stored as a generic text value cannot be indexed and queried with the same numeric range efficiency as a price field stored in a properly typed, dedicated numeric column, and this limitation persists regardless of how aggressively indexes are added to the generic, shared table structure.
This is precisely why indexing, while a valuable and necessary part of any performance optimization effort, ultimately hits a ceiling on directory platforms operating at real scale, and why genuinely resolving the meta table bottleneck requires a more fundamental architectural change rather than simply layering additional indexes onto a table structure that was never designed to support this kind of high volume, multi criteria filtering efficiently in the first place.
Why This Problem Compounds With Admin Dashboard Bloat
The meta table bottleneck does not only affect front end search performance. It also directly affects the administrative experience for the internal team managing listing content, since WordPress’s admin interface frequently needs to query and display custom field data across the same sprawling, shared table structure, whether displaying a sortable listing table, powering an admin side filter, or simply loading the edit screen for an individual listing that carries dozens of custom fields, each requiring its own lookup against the same generically structured table. On a directory platform with tens of thousands of listings, this admin side overhead becomes a genuine productivity drag on the internal team responsible for managing and updating listing content daily, compounding the front end search performance problem with a parallel, internally felt cost that similarly traces back to the same underlying architectural limitation.
How Complex Taxonomies Compound the Same Underlying Problem
Custom taxonomies, used to categorize listings by type, region, or any other hierarchical or non hierarchical classification scheme, introduce a parallel version of the same underlying architectural challenge. WordPress stores the relationship between a post and its assigned taxonomy terms across a set of shared, generically structured tables, and querying listings by taxonomy term, particularly when combining taxonomy filtering with the kind of custom field filtering described above, requires additional joins against these taxonomy relationship tables layered on top of the joins already required for custom field filtering. A directory platform with a rich, multi level taxonomy structure, several distinct classification schemes each with many possible terms, compounds the total number of joins a single, realistic multi criteria search query needs to perform, since taxonomy filtering and custom field filtering both draw from separate but similarly structured, similarly shared underlying tables.
This compounding effect means a directory platform with both a large volume of custom field data and a genuinely complex, multi dimensional taxonomy structure experiences the meta table bottleneck considerably more severely than a platform with either large volume or complex taxonomies alone, since the query cost of combining both filtering dimensions within a single search request grows multiplicatively rather than simply additively as both the underlying data volume and the taxonomy structure’s complexity increase together.
The Write Overhead of High Volume Listing Updates
Directory platforms are rarely static. Listings get added, updated, and removed continuously, sometimes at meaningful volume, particularly for platforms where individual businesses, agents, or sellers actively manage and update their own listings on an ongoing basis. Every update to a listing’s custom field data, under the default WordPress metadata structure, requires writing to the same large, shared table that every other listing’s custom field data also depends on, and at genuine directory scale, this write volume itself becomes a meaningful contributor to overall database load, competing directly with the read heavy search and filtering traffic that the same shared table is simultaneously trying to serve efficiently.
This write and read contention against the same underlying shared table represents an additional, often underappreciated dimension of the meta table bottleneck, since a table under heavy simultaneous read and write load experiences degraded performance on both sides of that load beyond what either the read traffic or the write traffic would produce in isolation. A properly refactored architecture, described in the following section, addresses this specific dimension of the problem directly by separating frequently written data from the read optimized structures that search and filtering functionality depends on, reducing this contention considerably.
Bespoke Database Refactoring
Resolving the meta table bottleneck at a genuine architectural level requires moving beyond the default, generic custom field storage structure entirely for the specific data that matters most to a directory platform’s core search and filtering functionality, replacing it with purpose built, properly structured database tables designed specifically around the platform’s actual data and actual query patterns.
Designing Custom Tables Around Actual Query Patterns
The foundation of bespoke database refactoring for a high volume directory involves designing dedicated database tables specifically structured around the listing attributes that are actually used for filtering, sorting, and searching, rather than continuing to rely on the generic, one size fits all custom field structure that WordPress provides by default. This means a price field lives in a properly typed numeric column, specifically indexed for efficient range queries. A location field is stored in a structure that supports efficient geographic or hierarchical queries, rather than as a generic text value. Boolean attributes, whether a listing has a specific amenity or feature, are stored as proper boolean columns rather than generic text values requiring string comparison during every filtered query.
This kind of dedicated table design requires genuine database architecture expertise, since it involves analyzing exactly how the platform’s search and filtering functionality actually queries listing data in practice, and designing a schema specifically optimized around those real, observed query patterns rather than a generic, one size fits all structure applied without regard for the platform’s actual usage. A directory platform where visitors primarily filter by price and location benefits from a schema optimized specifically around efficient range and geographic queries on those two attributes. A directory platform where visitors commonly apply numerous simultaneous boolean filters, specific amenities, specific features, benefits from a schema design specifically optimized to handle efficient multi criteria boolean filtering instead, a genuinely different optimization target requiring a genuinely different underlying table design.
Bypassing WordPress Metadata Constraints Without Breaking Compatibility
A critical consideration in this kind of refactoring is maintaining compatibility with the broader WordPress ecosystem the platform still depends on, plugins, the admin interface, any existing integrations, while bypassing the specific performance constraints of the default metadata structure for the platform’s core search functionality. This typically involves a carefully designed synchronization layer, where listing data continues to be entered and managed through familiar WordPress admin interfaces and custom field structures for editorial convenience, while a properly structured, purpose built set of dedicated tables is maintained in parallel specifically to power fast, efficient search and filtering, kept synchronized automatically whenever the underlying listing data changes.
This dual structure approach, preserving a familiar, WordPress native editing experience for the content team while running search and filtering against a genuinely optimized, purpose built database structure behind the scenes, represents the practical reality of how bespoke database refactoring is typically implemented on a real, actively used directory platform, rather than requiring a disruptive, all or nothing migration away from WordPress’s native content management capabilities entirely.
Refactoring Complex Listing Metrics Into Dedicated Structures
Many directory platforms track metrics beyond simple static listing attributes, view counts, inquiry counts, historical price changes, availability status changes over time, data that is inherently more complex and more frequently updated than a listing’s core static attributes. Storing this kind of frequently changing, metric oriented data within the same generic custom field structure used for static attributes compounds the performance problem considerably, since these metrics are typically updated far more frequently than static listing details, generating substantial additional write load against an already strained shared table structure.
Bespoke refactoring addresses this by creating entirely separate, purpose built tables specifically designed for this kind of metric and historical data, structured to handle frequent writes efficiently while remaining properly indexed for whatever reporting or sorting functionality the platform needs to support, such as sorting listings by popularity or recent activity. Separating this frequently changing metric data from more static listing attributes into its own dedicated structure prevents the write heavy nature of metric tracking from further degrading the read heavy performance of the platform’s core search and filtering functionality, addressing two genuinely different data access patterns with two genuinely different, purpose built table structures rather than forcing both into the same generic, one size fits all metadata table.
Migration Strategy for an Actively Used Platform
Refactoring a directory platform’s database architecture while it remains actively used by real visitors and real listing administrators requires a carefully staged migration approach, rather than a disruptive, all at once cutover that risks significant downtime or data inconsistency during the transition. This typically involves building and populating the new, purpose built table structure alongside the existing system, running both in parallel while the new structure’s accuracy and performance are thoroughly verified against real production data and real production query patterns, before gradually cutting search and filtering functionality over to the new, optimized structure, with the ability to roll back cleanly if any unexpected issue surfaces during this careful, staged transition.
This staged approach, while requiring more careful planning than a simpler, disruptive migration, is precisely what allows a genuinely business critical directory platform to undergo this kind of fundamental architectural refactoring without the platform’s core search functionality, exactly the functionality visitors depend on every single day, ever experiencing meaningful disruption during the transition itself.
Refactoring Taxonomy Relationships for Complex Classification Schemes
Just as static listing attributes benefit from being moved into dedicated, purpose built tables, complex taxonomy structures, particularly those involving multiple, independently filterable classification dimensions, benefit from a similarly deliberate refactoring approach. Rather than relying entirely on WordPress’s default, generic taxonomy relationship tables for every classification dimension a listing carries, a bespoke refactoring effort identifies which specific taxonomy dimensions are most heavily used in actual search and filtering traffic, and builds dedicated, properly indexed structures specifically optimized for combining those particular classification dimensions efficiently with the platform’s other core filterable attributes.
This targeted approach, rather than attempting to refactor every conceivable taxonomy structure uniformly regardless of actual usage, allows engineering effort to be concentrated specifically on the classification dimensions that genuinely drive the majority of real search traffic, delivering the largest practical performance improvement for the effort invested, while less heavily used taxonomy structures can often continue relying on WordPress’s default handling without meaningfully affecting overall platform performance, since their query volume never approaches the scale where the default structure’s limitations become genuinely significant.
Maintaining Data Integrity Across the Synchronization Layer
A dual structure approach, maintaining both a WordPress native editing experience and a purpose built, optimized search structure in parallel, introduces a genuine engineering responsibility around keeping these two structures reliably synchronized, ensuring that any update made through the familiar WordPress admin interface is promptly and accurately reflected in the optimized structure that search and filtering functionality actually depends on. A synchronization failure, however brief, risks a scenario where search results reflect outdated or incorrect listing data relative to what the WordPress native editing interface currently shows, undermining trust in the platform’s search accuracy in a way that would represent a serious problem for any directory business.
Properly engineered synchronization includes both real time updates triggered immediately whenever a listing changes through the standard editing interface, and periodic reconciliation processes that compare the two structures against each other on a regular schedule, catching and correcting any discrepancy that might have slipped through the real time synchronization mechanism due to an unusual edge case, a failed process, or an unexpected error during a particular update. This combination of real time synchronization and periodic reconciliation is what allows the dual structure approach to deliver genuine, trustworthy accuracy alongside its substantial performance benefit, rather than trading search speed for a meaningful risk of search results silently drifting out of sync with the platform’s actual, current listing data.
Custom WP Search Logic
Beyond the underlying database structure, the actual search logic used to query that structure represents a second, closely related area where default WordPress behavior falls short of what a genuinely high performance directory platform requires, and where custom, purpose built search logic delivers a substantial, measurable improvement.
Why Default WordPress Search Was Never Built for This
WordPress’s built in search functionality was designed primarily around searching post titles and content, a reasonable default for a typical blog or content site, but fundamentally mismatched to the actual search requirements of a directory platform, where visitors are searching and filtering based on structured attributes, price, location, category, specific features, rather than free text content matching. Default WordPress search, when adapted or extended to attempt this kind of structured, multi criteria filtering, inherits the same underlying meta table query pattern described earlier in this article, joining the same generic, shared metadata table repeatedly for every filter criterion applied, producing exactly the kind of slow, expensive query pattern that becomes untenable at real directory scale.
Recognizing this mismatch is an important first step, since many directory platforms continue relying on default or lightly modified WordPress search functionality well past the point where it can genuinely support the platform’s actual scale, simply because the underlying limitation is not always obvious until search performance has already degraded to a genuinely painful degree, directly affecting visitor experience and conversion on a platform where fast, precise search is often the single most important feature the entire business proposition depends on.
Building Custom Indexed Search Against the Refactored Structure
Once a directory platform’s core listing attributes have been refactored into properly structured, purpose built database tables as described in the previous section, custom search logic can be built specifically to query this optimized structure directly, entirely bypassing the expensive, repeated joins against WordPress’s generic metadata table that default search functionality depends on. This custom search logic is written specifically around the platform’s actual filtering requirements, querying properly typed, properly indexed columns directly rather than performing the kind of generic, type agnostic string matching that the default metadata structure requires.
The performance difference this produces is often dramatic, since querying a properly indexed, purpose built numeric column for a price range is a fundamentally faster database operation than joining a generic, shared metadata table and performing string based comparison against text stored values, particularly once that comparison needs to happen against a table containing millions of rows across a directory platform’s full listing history. This is precisely why custom search logic, built specifically around a properly refactored database structure, represents the second essential half of genuinely solving the performance problem this article has described throughout, since even a perfectly refactored database structure delivers limited real world benefit if the search logic actually querying it continues relying on the same generic, inefficient query patterns the refactoring was specifically meant to move away from.
Implementing Dedicated Search Infrastructure for Extreme Scale
For directory platforms operating at the very largest end of the scale spectrum, tens of thousands of listings with genuinely complex, high volume, multi criteria search traffic, even a well optimized custom database query approach eventually benefits from a dedicated search infrastructure layer, using a purpose built search engine specifically designed for exactly this kind of fast, multi criteria filtering at scale, running alongside the platform’s primary database rather than replacing it entirely. This kind of dedicated search infrastructure maintains its own specifically optimized index of listing data, kept synchronized with the primary database whenever listings change, and is specifically architected to handle the kind of complex, simultaneous, multi criteria filtering that even a well refactored relational database structure eventually strains under at truly extreme scale.
Implementing this kind of dedicated search layer represents a further, more substantial architectural investment beyond the database refactoring described earlier, and is generally most relevant for the largest, most search intensive directory platforms specifically, where search query volume and complexity have grown to the point where even a properly optimized relational database query approach no longer delivers the search response time the platform’s scale and business requirements genuinely demand.
Balancing Search Precision Against Query Complexity
A genuinely well designed custom search implementation also involves careful consideration of how search precision and query complexity interact, since supporting an increasingly rich, increasingly flexible set of filter combinations inherently increases the complexity of the underlying search logic required to handle every possible combination efficiently. Custom search logic needs to be designed deliberately around the platform’s actual, real world filter usage patterns, prioritizing genuinely efficient handling of the filter combinations visitors actually use most frequently, rather than attempting to optimize uniformly across every theoretically possible filter combination regardless of how rarely certain combinations are actually used in practice.
This kind of usage pattern analysis, understanding which specific filter combinations actually drive the majority of real search traffic, allows custom search logic to be prioritized and optimized deliberately around genuine, measured usage rather than a purely theoretical, comprehensive approach that might spread optimization effort too thinly across filter combinations that rarely, if ever, actually occur in real visitor behavior.
Default WordPress Handling Versus Bespoke Directory Architecture
| What You Care About | Default WordPress Metadata and Search | Bespoke Directory Architecture |
|---|---|---|
| Custom field storage | Generic shared table, text values | Dedicated, properly typed columns |
| Multi filter search queries | Repeated joins against a shared table | Direct queries against indexed columns |
| Taxonomy and attribute combination | Multiplying joins across relationship tables | Purpose built structures for common combinations |
| Admin dashboard responsiveness at scale | Degrades as listing volume grows | Stays responsive through dedicated structures |
| Write and read contention | Shared table under simultaneous load | Separated read and write optimized structures |
| Scaling ceiling | Degrades noticeably past tens of thousands of listings | Built specifically to support continued growth |
Real World Scalability
The architectural principles described throughout this article are not theoretical. They reflect the genuine engineering challenges faced by real, large scale directory and listing platforms operating at meaningful volume, and understanding a concrete, real world example of this scale helps ground the discussion in what these principles actually need to support in practice.
What Real Scale Actually Looks Like for a Directory Platform
Consider a specialized real estate portal like Metrocuadrado, a large scale property listing platform serving the Colombian real estate market, built on WordPress and operating at exactly the kind of scale this article has focused on throughout, a platform carrying a substantial volume of active property listings across a national market, each listing carrying a rich set of structured attributes, price, location, property type, square footage, amenities, and each needing to be searchable and filterable quickly by visitors actively comparing properties across a wide range of simultaneous criteria. Platforms operating at this scale represent exactly the kind of environment where the meta table bottleneck described at the start of this article becomes a genuine, business critical constraint rather than a theoretical concern, since search performance directly affects whether visitors can actually find and engage with relevant listings, which in turn directly affects the platform’s core business value to both property seekers and the real estate professionals and agencies whose listings depend on being discoverable.
A platform of this scale and complexity illustrates precisely why the bespoke database refactoring and custom search logic described throughout this article represent genuine architectural necessities rather than optional performance tuning, since a national real estate portal serving a genuinely large, active market simply cannot rely on default WordPress metadata handling and default search functionality to deliver the kind of fast, precise, multi criteria search experience that both property seekers and the business itself depend on for the platform to remain competitive and genuinely useful at this scale.
Why This Level of Scale Requires Purpose Built Architecture From the Start
Platforms operating at genuine national or regional directory scale illustrate why the architectural principles described throughout this article are not simply a performance optimization applied after the fact, but a foundational requirement that needs to be considered from relatively early in a platform’s growth trajectory, well before the platform has actually reached its full eventual scale. A directory platform that waits until it has already accumulated tens of thousands of listings on an unoptimized, default WordPress metadata structure before addressing this architectural gap faces a considerably more complex and more urgent refactoring effort than a platform that begins planning for this kind of purpose built architecture proactively, while listing volume is still growing toward, rather than having already substantially exceeded, the point where default WordPress metadata handling becomes a genuine performance liability.
The Broader Pattern Across Directory and Catalog Platforms
While large scale real estate platforms represent a particularly clear illustration of this pattern, the same underlying architectural principles apply broadly across any WordPress powered directory, listing, or catalog platform operating at meaningful scale, whether a business directory, a job listing platform, a large product catalog, or any other structured, high volume content type where visitors depend on fast, precise, multi criteria filtering to find genuinely relevant results among a large underlying dataset. The specific attributes being filtered, the specific search patterns visitors actually use, and the specific scale a given platform needs to support will vary considerably across these different use cases, but the fundamental architectural challenge, and the fundamental architectural solution, the meta table bottleneck, bespoke database refactoring, and custom search logic built specifically around a purpose built table structure, remains consistent across this entire category of high volume, structured content platform.
What This Looks Like in Practice
Consider a growing business directory platform that began several years earlier with a few hundred business listings and has since grown to over forty thousand active listings across a wide range of categories, each carrying detailed structured attributes, business category, service area, pricing tier, customer ratings, and a range of boolean feature flags indicating specific services offered. The platform’s product manager has been fielding increasingly frequent complaints about slow search results, particularly whenever visitors apply several simultaneous filters, a pattern that has become the platform’s most common search behavior as the directory’s category and feature filtering options have grown richer over time.
A thorough architectural review confirms the meta table bottleneck described throughout this article as the primary cause, with search queries applying four or more simultaneous filters requiring repeated joins against a metadata table that has grown to contain several million rows across the platform’s full listing and attribute history. Bespoke database refactoring creates dedicated, properly typed tables specifically for the platform’s core filterable attributes, category, service area, pricing tier, and feature flags, each structured and indexed specifically around how visitors actually query them in practice. Custom search logic is built specifically against this new, purpose built structure, replacing the platform’s previous reliance on extended default WordPress search functionality entirely for the platform’s core filtering and search functionality. The combined effect reduces typical multi criteria search response time dramatically, transforming what had become the platform’s most consistently complained about pain point into a genuinely fast, responsive search experience capable of comfortably supporting the platform’s continued growth well beyond its current forty thousand listing scale.
A Second Scenario: A Large Product Catalog Facing the Same Underlying Pattern
Consider a different case, a specialty ecommerce business running a product catalog that has grown to over sixty thousand individual product listings across a wide range of categories, each carrying detailed structured attributes, material, dimensions, compatibility specifications, and availability status across multiple warehouse locations. The business had assumed its slow product filtering performance was a hosting capacity issue, and had already upgraded its hosting plan twice without meaningful improvement, following the same hosting upsell pattern described in our broader guidance on server resource optimization, before finally investigating the underlying database architecture directly.
The investigation confirmed the meta table bottleneck as the actual root cause, with product filtering by compatibility specification and availability status, the platform’s two most commonly combined filter criteria, requiring expensive joins against a metadata table that had grown considerably larger than the actual product catalog itself, since each product carried numerous individual attribute values all stored within the same shared structure. Bespoke refactoring created dedicated tables specifically for compatibility specifications and multi location availability data, the two dimensions driving the overwhelming majority of the platform’s actual filter traffic, while custom search logic was built specifically to query this new structure directly. The result allowed the business to actually downgrade its hosting plan back to a smaller, less expensive tier following the refactoring, since the underlying query inefficiency, not genuine server capacity, had been the actual cause of the performance problems the previous hosting upgrades had failed to resolve.
A Checklist for Product Managers Evaluating Directory Performance
For product managers trying to determine whether their own directory or catalog platform is approaching or has already crossed this specific architectural threshold, a few direct questions help surface the answer. Has search response time noticeably degraded as the platform’s total listing count has grown over time, particularly for searches applying several simultaneous filter criteria rather than a single, simple filter. Does the platform’s admin dashboard feel noticeably slower when browsing, sorting, or filtering the full listing catalog compared to how it performed when the platform carried meaningfully fewer listings. Is the platform currently relying primarily on default or lightly modified WordPress custom field storage and search functionality for its core filtering and search experience, rather than a purpose built, dedicated database structure. And has the platform’s listing volume grown substantially since its original architecture was first established, without a corresponding architectural review to confirm that original design still genuinely supports the platform’s current, larger scale.
A single yes among these questions suggests a specific, addressable architectural gap worth investigating further. Multiple yes answers, particularly a documented pattern of search performance degrading in direct correlation with listing volume growth, indicate that the platform has very likely already crossed the threshold where default WordPress metadata handling can no longer efficiently support its actual, current scale, representing exactly the kind of architectural gap that bespoke database refactoring and custom search logic are specifically designed to resolve.
Frequently Asked Questions About Scaling Custom Post Types and Taxonomies
At what listing volume does the meta table bottleneck typically become a genuine problem
This depends considerably on the specific number of custom fields per listing and the complexity of the filtering visitors actually apply, but many platforms begin noticing meaningful search performance degradation somewhere in the range of ten to twenty thousand listings, particularly once visitors are commonly applying several simultaneous filter criteria rather than simple, single attribute searches. Platforms with fewer custom fields per listing or simpler filtering requirements may comfortably scale considerably further before encountering this specific bottleneck, while platforms with especially rich, complex attribute sets may encounter it at meaningfully lower listing volumes.
Does bespoke database refactoring require abandoning WordPress custom post types and taxonomies entirely
No. The refactoring described throughout this article specifically targets how filterable attribute data is stored and queried for search and filtering purposes, while custom post types and taxonomies continue to serve their normal role in organizing and managing content through WordPress’s native admin interface. The dual structure approach described earlier in this article, maintaining familiar WordPress native content management alongside a purpose built, optimized structure specifically for search performance, is precisely designed to preserve the benefits of WordPress’s native content management capabilities while resolving the specific performance limitation of its default metadata storage approach.
Will this kind of database refactoring disrupt search engine rankings the directory platform has already built up
Properly executed refactoring, focused specifically on the underlying database structure and search query logic rather than the platform’s actual URLs, content structure, or public facing pages, should have no direct impact on existing search engine rankings, since the visible content and URL structure that search engines have already indexed remains unchanged. Careful attention during the migration process, verifying that public facing pages continue to render correctly and consistently throughout the staged transition described earlier in this article, is nonetheless an important part of ensuring this refactoring work does not inadvertently introduce any disruption to the platform’s existing search visibility.
How does this kind of database refactoring relate to general WordPress database query optimization
The database query tuning principles described in our broader guidance on server resource optimization, proper indexing, efficient query structure, avoiding unnecessary repeated queries, apply directly to the custom, purpose built tables described throughout this article as well. Bespoke database refactoring for directory platforms represents a specific, more architecturally involved application of these same underlying database performance principles, applied specifically to the unique challenge of high volume, multi criteria structured content filtering that generic WordPress metadata handling was never designed to support efficiently at real directory scale.
Is this level of architectural investment worthwhile for a directory platform that has not yet reached tens of thousands of listings
For a platform with genuine, realistic growth ambitions toward this kind of scale, addressing the underlying architecture proactively, before listing volume has already grown large enough for the meta table bottleneck to become a painful, visible problem, is generally considerably less disruptive and less costly than waiting until the platform has already scaled substantially on an unoptimized foundation. For a smaller platform with more modest, stable growth expectations, this level of architectural investment may reasonably be deferred until listing volume and filtering complexity genuinely approach the threshold where default WordPress metadata handling begins to show measurable strain.
How long does a bespoke database refactoring project typically take for a directory platform at real scale
The timeline depends considerably on the platform’s specific complexity, the number of distinct filterable attributes involved, and the complexity of its taxonomy structure, but a thorough project generally includes a careful analysis phase to identify actual query patterns, a schema design phase for the new purpose built structure, a synchronization layer implementation, and the staged migration process described earlier in this article, run against real production data with careful verification at each stage before any final cutover. Rushing this process to compress the timeline generally increases risk considerably, since the staged, carefully verified approach is specifically what protects a business critical directory platform from disruption during the transition.
Does this kind of refactoring work require replacing the platform’s existing plugins entirely, such as a real estate or directory listing plugin
Not necessarily. Many directory and listing plugins provide valuable functionality around content management, front end display, and administrative workflow that a business genuinely wants to retain. Bespoke refactoring typically targets specifically how filterable search data is stored and queried underneath these plugins, often working alongside the existing plugin’s data structures through the synchronization layer described earlier, rather than requiring the plugin itself to be removed or replaced, though the specific approach depends on how a given plugin’s own architecture is structured and how much flexibility it provides for this kind of underlying performance optimization.
How do we know whether our specific performance problem is actually the meta table bottleneck versus a different underlying cause
The clearest diagnostic signal is whether search response time correlates specifically with the number of simultaneous filter criteria applied, meaning a single filter search performs acceptably while adding several additional simultaneous filters produces a disproportionate slowdown, combined with correlation against total listing volume, meaning the same multi filter search has become progressively slower as the platform’s total listing count has grown over time. This specific pattern, disproportionate slowdown with both increased filter complexity and increased data volume together, is a strong indicator of the meta table bottleneck specifically, though a proper technical audit, profiling actual database queries directly, remains the definitive way to confirm this diagnosis with certainty.
How does bespoke database refactoring for directories relate to the general database query tuning covered in your server optimization guidance
The two are closely related and complementary. General database query tuning, covered in our broader guidance on server resource optimization, addresses inefficient queries and missing indexes across a site’s overall codebase. Bespoke database refactoring for directory platforms applies these same underlying performance principles specifically to the unique architectural challenge of high volume, multi criteria structured content filtering, going a step further than general query tuning alone by restructuring the underlying data storage itself, not just optimizing how existing queries run against the existing, generic structure. A directory platform benefits from both, general query tuning across its broader codebase and this more specialized, architecturally involved refactoring specifically applied to its core listing and search functionality.
If Your High Volume Directory Has Outgrown Standard Plugins
The meta table bottleneck described throughout this article is not a failure of WordPress as a platform. It is a predictable, well understood limitation of a default storage mechanism that was never designed to support tens of thousands of richly structured, heavily filtered listings efficiently, and resolving it genuinely requires code level engineering, bespoke database refactoring designed specifically around a platform’s actual query patterns, and custom search logic built specifically to query that refactored structure efficiently, not a generic plugin installation or a surface level configuration adjustment. Directory, listing, and catalog platforms operating at real scale, or growing deliberately toward it, need a technical partner who understands WordPress database architecture at exactly this level of depth, capable of designing and implementing the kind of purpose built, bespoke architecture that genuine directory scale actually requires.
Why This Is Fundamentally an Engineering Partnership, Not a Single Project
It is worth being direct about how this kind of work fits into an ongoing relationship rather than a single, isolated engagement. A directory platform’s listing volume, taxonomy structure, and filtering requirements continue to evolve as the business grows, new categories get added, new filterable attributes get introduced in response to changing market needs, and search usage patterns themselves shift over time as the platform’s audience and use cases mature. A bespoke architecture built correctly today needs periodic review and, in many cases, incremental extension as these underlying requirements continue to change, which is precisely why this kind of deep architectural work benefits from an ongoing engineering partnership, capable of returning to extend and refine the platform’s search and data architecture as genuine business needs evolve, rather than treating the initial refactoring as a single, final, permanently complete solution.
This is exactly the kind of specialized, ongoing technical relationship that a resolution based support model is built to sustain, giving a growing directory platform predictable, ongoing access to genuine database architecture expertise as its scale and complexity continue to grow, rather than needing to negotiate a new, separately scoped engagement every time the platform’s evolving business requirements introduce a new filtering dimension or a new category of listing data that the original architecture was not specifically designed to anticipate.
Recognizing the Signal Before It Becomes a Crisis
The businesses that navigate this architectural transition most successfully are consistently the ones that recognize the early warning signs, search response time beginning to degrade specifically as listing volume and filter complexity grow together, before that degradation has become severe enough to meaningfully affect conversion rates or user trust in the platform’s core search functionality. A directory platform’s search experience is very often the single most important feature the entire business depends on, the mechanism through which visitors actually discover the specific listings relevant to their needs among a large, otherwise overwhelming catalog. Treating the architectural foundation beneath that core search experience as a genuine engineering priority, addressed proactively as the platform scales rather than reactively once performance has already become a visible, painful business problem, is what separates directory platforms that scale smoothly into genuine market leaders from those that find their own growth quietly working against them, one increasingly slow search query at a time.
If Your High Volume Directory Has Outgrown Standard Plugins
You need a code level engineering partner. Get an instant WordPress audit or consult with us to refactor your database architecture.
